I Built a Factory to Finish What AI Started
BESF began with checking AI-generated apps. The larger ambition is a business loop: research, build, reach customers, deliver value and learn what to change.
An imagined workshop. The software checks and evidence follow below.AI-generated conceptual setting.
I want to spend less of my time moving work between tools. An idea becomes a brief, the brief becomes an app, the app needs customers, and their questions become the next round of work. I want AI to carry more of that process, with me supplying the direction and changing it when I learn something.
That is the ambition behind BESF. It started with a smaller problem: AI could produce a convincing app quickly, but I still had to finish it. Buttons did nothing. Screens were missing. Work disappeared when the page reloaded. Then I went through the same process on the next app.
I wanted those fixes to survive beyond one project. Once I had found a mistake, the next build should know to look for it.
Getting beyond the first draft
VibeCord, my project for creating Discord bots from a description, made this concrete. Generating the code was only part of the job. Someone still had to get from their request to a bot they could actually use.
BESF takes a short idea, works out what needs to happen, builds it and checks the result. If something fails, it sends the work back for repair. The agent doing the repair cannot simply declare the problem solved.
THE APP FACTORY
An idea goes in. Proof has to come out.
AI made first drafts quickly. I built the factory to do the slow part: define, check and finish them.
- 01PlanDefine what must workroutes · actions · data
- 02BuildGive specialists small jobs29 roles · used as needed
- 03InspectTry every promisebuttons · login · reload
- 04ProveKeep only repeatable evidencetests · journeys · build
- RUN 1122
- RUN 2124
- RUN 311
- RUN 40
SignalDeck went through the line
I tried this on SignalDeck, a small app for collecting signals and ideas. Its recorded checks went from 122 problems to zero locally, with stricter inspection finding more problems along the way. The hosted version still needed its own checks before I could trust it with real users.
It also took more AI work than I wanted. The useful result was that the system kept track of what remained unfinished and worked through it. I had not yet made that process cheap.
ONE RECORDED BUILD
A higher count revealed a better inspection.
Stricter inspection raised SignalDeck's recorded count from 122 to 124. Focused repair then reduced the local checklist to zero.
- 01 · First build122
- 02 · Stricter inspection124
- 03 · Focused repair11
- 04 · Local pass0
Stricter inspection expanded what the system could see.
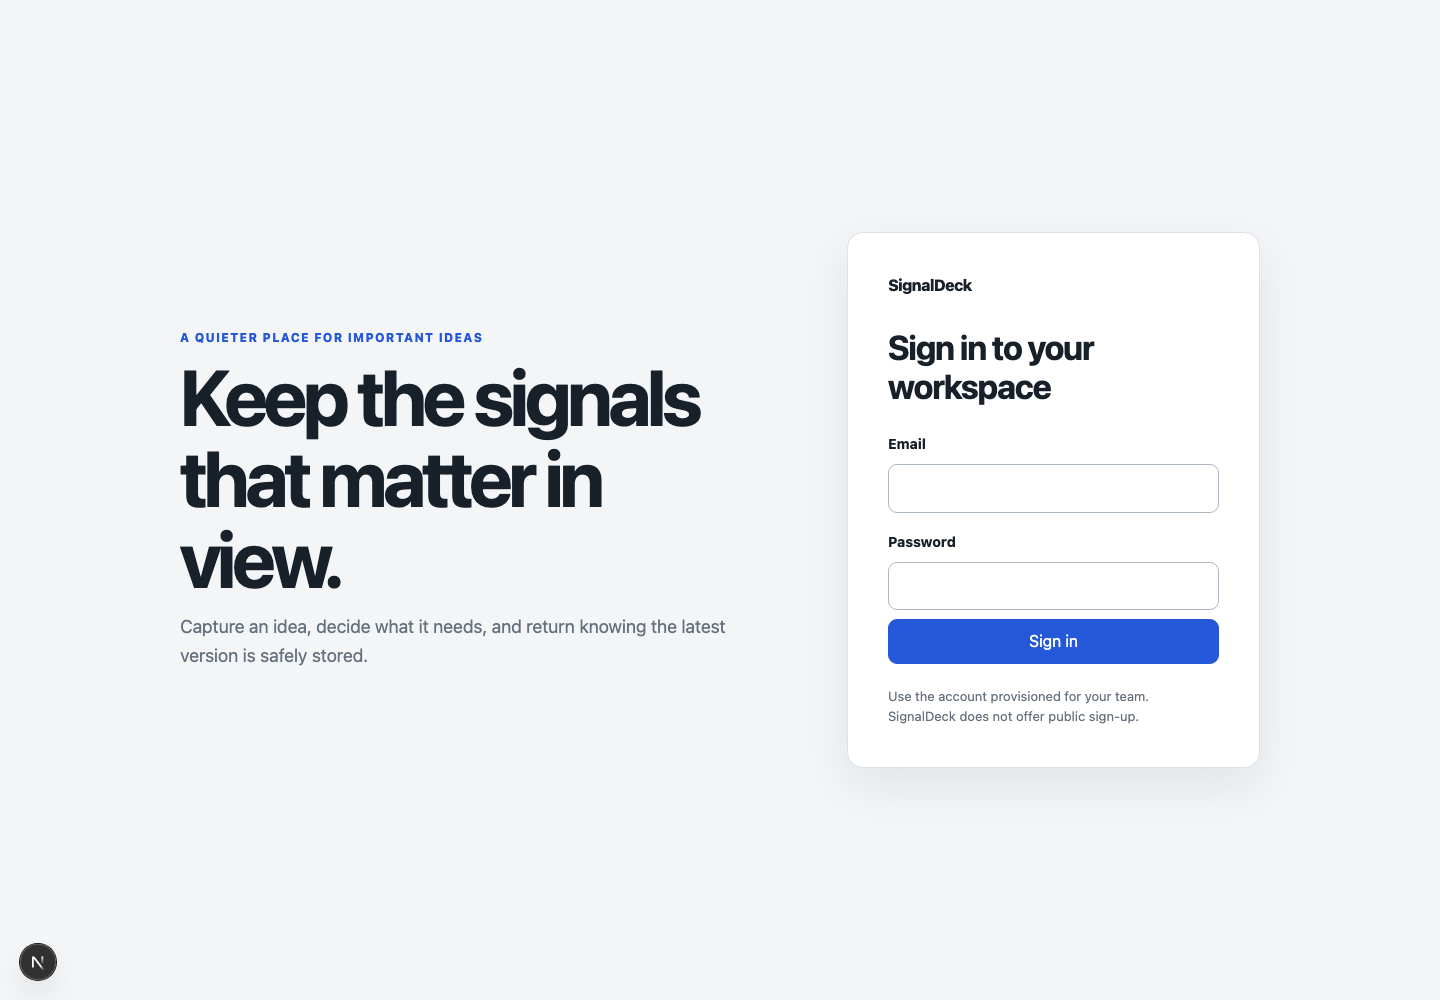
- Surface
- five routes · seven stories · 27 actions
- Local record
- 109 tests passed · contract · type · lint · build
- Prepared
- 102 browser cases across mobile, tablet and desktop
The technical record and AI cost
The four recorded audits found 122, 124, 11 and then zero local checklist failures. The increase to 124 came from stricter inspection.
The app covered five routes, seven user stories and 27 actions. Its local record contained 109 passing automated tests, a contract audit, typecheck, lint and build, plus 102 prepared browser cases. Hosted login, saved data and access rules remained unproven. Two low-reasoning calls used 2.58 million and 891,000 input tokens and still left work unfinished.
The repair path below makes one failure concrete: someone should be able to leave the app and come back without losing their work.
WHEN THE FACTORY FINDS A FAULT
It repairs the work. It cannot mark itself correct.
The app loses someone’s work. The system finds the problem, asks for a repair and checks whether the person can now leave and come back safely.
PERSIST-03- 01CHECK CATCHES ITReload test fails
Expected saved data. Found an empty state.
FAIL · PERSIST-03 - 02EVIDENCE BECOMES A LISTWhat needs to work
- Keep what the person saved
- Bring it back when they return
- Keep other people’s work private
- 03REPAIR THE PROBLEMRepairs only this fault
Fix the lost work without changing unrelated parts of the app.
SCOPE · PERSISTENCE - 04SAME CHECK, AGAINReload test reruns
Leave the app and return. Is the saved work still there?
RUN · PERSIST-03
- 01Static + unitfast · every change
- 02Browser journeyafter local checks pass
- 03Live proofafter the exact build ships
The business needs two feedback loops
A working app can still be something nobody wants. That is where I want to take this next: connect the building process to the people using—and paying for—the product.
The idea comes from feedback control: observe the result of an action, then use it to adjust what happens next. In a business, Eric Ries’s build–measure–learn gives this a practical form. Try something small enough to learn from, watch what customers actually do, and let that change the plan.
Find a problem → try an offer → deliver it → learn from customers.
Build → check → repair → check again.
What customers do changes what gets built next.
The timing matters. I can check a code change in seconds. Finding out whether someone returns to a product takes longer. An agent that keeps changing the offer after every click could make it harder to learn anything.
What that means for my products
Did the demonstration help someone make a useful bot for their group?
Repeated blocks and capability requests should shape the next build.Did an alert lead to something useful, or did people keep ignoring it?
Sending more notifications would not answer that question.Did the last-seen clue help someone find the object?
A past sighting is a clue, not a live location.These are the business experiments I want to connect. I can reuse the machinery across projects, but I still have to learn what matters to each set of customers.
Where Meta ads fit
Say I have a VibeCord demo that shows a bot doing something useful. AI could help turn it into a few different ads, prepare the pages those ads lead to, and run a test within an agreed budget. Meta already automates parts of campaign delivery through Advantage+.
I want to follow what happens after the click. Did the person make a bot? Did it work? Did they come back? Those answers could lead to a better ad, a clearer explanation, or a change to the product itself.
A useful write-up, a search result, a referral or a conversation in the right community could start the same process. Content Machine is one piece I am building for turning the actual work into material people can see.
THE SECOND OUTPUT
One real build. Many useful stories.
The factory keeps evidence while it works. That evidence can become content—without inventing a success story afterwards.
- PROBLEM
- Context was getting lost.
- FAILED
- 122 checks
- RESULT
- 0 local failures
- screenswhat changed
- failureswhat broke
- proofwhat passed
Same evidence. Different shape.
- Instagramvisual story · connected · gatedsaves + replies
- TikTokshort demo · draft hand-offcomments + holds
- Reddituseful write-up · rules + reviewquestions + critique
- Xbuild thread · auth requiredreplies + shares
Questions, objections and real usage go back to the idea queue.
I have not yet proven this complete commercial cycle. When I do test it, the costs need to include advertising, AI, support and refunds. An ad can look successful while the business loses money. And a sale credited to an ad is not necessarily a sale the ad caused; a comparison group can help answer that.
Other people are pursuing this too
Polsia is the closest example I found. Its founder describes agents handling engineering, Meta ads, research, support and payments. His account of building it also includes a broken support route that left disputes unanswered. That is a concrete example of how much has to stay connected. These are founder-reported results.
Anthropic and Andon Labs tried running a shop with Claude. Better tools and procedures helped, but adding an AI manager introduced problems of its own. Humans still approved purchases. I find that experiment useful because it shows what happened when the agents had a business to operate, including the parts that went wrong.
More examples and sources
Bartosz Cruz describes agents for ads, research, publishing and reporting, with strategy remaining human-led. Like Polsia, this is an operator’s account rather than an independent audit.
The research included Polsia’s founder on X and this Reddit discussion about AI managing Meta ads. The Reddit thread mixes practical questions with people promoting their own tools. Neither social activity nor a launch announcement establishes a profitable autonomous business. Sources reviewed 10 September 2026.
What if this just creates more work?
That is a fair objection. Builders on Reddit describe agents that work in demos but struggle with real customers. Others point out that making software easier to build does not make it easier to sell. My local checks answer whether parts of an app work. They do not yet show that this whole arrangement saves me time or earns its keep.
There is a writing version of the same problem. Reddit readers describe fluent paragraphs that add very little, while Charlotte Alter argues on X that readers want another person’s experience and insight. That applies to this article too. I supply the ideas and intent; AI helps communicate them. If the result keeps explaining the same thing, a nicer diagram does not rescue it. Each section needs to contribute an example, evidence or a consequence worth reading.
Better model alignment is part of my approach: the model needs to follow my intent and constraints even when a webpage or tool response tells it to do something else. OpenAI reports improvements from training models to resolve those instruction conflicts. That is evidence of progress on a specific problem, not a promise that each new model will behave better in every situation.
BESF already puts checks between building and accepting the work. For the wider business, I want to pair improving models with evaluations of the actual jobs, limits on what tools can do, and a way to stop and recover when something goes wrong. More autonomy should follow evidence that the system handles the work reliably. I have not yet demonstrated that across the complete business.
How I would test whether more autonomy is deserved
An evaluation, or eval, gives the agent a task and checks the result. Anthropic’s guide recommends combining code checks, model grading and human review, repeating trials, and checking what actually happened. A model saying it succeeded is not enough; a model judging another model can also miss the problem.
For my products, I want those tests to cover situations like these:
- A VibeCord repair: the bot performs the requested action, existing behaviour still works, and the repair stays within its allowed scope. Repeat the task and compare time, AI cost and my interventions with the previous approach.
- An advertising experiment: the agent stays within the approved budget, pauses when its stopping condition is met, and cannot quietly expand its spending permissions. Judge the experiment by useful customer activity and costs, not the number of ads produced.
- An article: it preserves my point, supports factual claims and adds useful information as it goes. A model review can flag repetition; asking a reader to explain the idea back tests something the model’s score cannot establish.
These are proposed extensions, not completed evaluations. I would keep unfamiliar cases for checking changes, turn failures into regression tests, and rerun them when the model or workflow changes. Live outcomes still matter: a good test score cannot establish demand or profitability.
Alignment also needs controls outside the model. In its August 2026 incident response, Anthropic described both alignment and containment failures during evaluations with cyber safeguards reduced, and added layers of monitoring and isolation. I take that as a reason to test the surrounding system as carefully as the model. Permissions, spending caps and recovery should remain effective when the model makes a bad decision.
What I want to stop doing by hand
I want a customer’s problem to travel further without me carrying it through every step: from research to a product change, from that change to a demonstration, and from the demonstration back to what customers do next.
My role can change as the system gets better. I want to give it more decisions when it can handle them, rather than remain the person approving every small task. The test is whether it delivers useful work with less intervention, and whether I can still understand and correct its mistakes.
That is what I am trying to build across these projects. BESF is the beginning of it.
How the projects fit together
Portarium handles control over agent actions. JustSwipe provides a phone interface for decisions; it is not wired into BESF yet. Content Machine prepares media, and Calvin Ops keeps the context. The map shows how I intend these pieces to work together.
NOT SIX RANDOM PROJECTS
One loop, built in pieces.
Each project addresses a different part of the work. This map shows how I intend them to fit together; the complete loop still needs proof.
VibeCoord supplied production lessons. BESF builds and proves the app. Portarium provides control boundaries. JustSwipe carries human decisions. Content Machine packages evidence. Calvin Ops keeps signals and returns results to the next build.
- 01PRESSURE TESTVibeCoord
Showed that a green-looking agent build can still fail the real user journey.
LESSON KEPT - 02BUILD + PROOFBESF
Turns each promise into a contract, a check and a bounded repair loop.
LOCAL PROOF - 03CONTROLPortarium
Separates what can run, what must pause and what should be blocked.
FOUNDATION - 04HUMAN STEERINGJustSwipe
Compresses taste, scope and review decisions into one phone-sized card.
STANDALONE - 05PACKAGEContent Machine
Turns real build evidence into review-ready video and social assets.
WORKING - 06MEMORY + RETURNCalvin Ops
Keeps the signals, approvals and results that should shape the next build.
IN PROGRESS
How research could become the next idea
The sources include problems in my own work, customer conversations, support messages and recurring questions on Reddit and X. I want each idea to retain where it came from so I can investigate it before deciding to build.
CONCEPTUAL FLOW · WHAT ENTERS THE FACTORY?
The factory needs ears.
This is the intended research flow. I want real problems to decide what gets built. Every launch should create better product decisions and honest material for my personal brand.
- MEMy workproblems I keep hitting
- USUserscalls · support · surveys
- R/Redditrepeated public pain
- XXquestions · complaints
Group repeats. Keep the source. Rank the pain.
Useful signals get saved—then lose their context.
Smallest test: one place to capture, group and revisit them.
- PAIN
- To assess
- PROOF
- To gather
Ship → watch → revise
Usage, replies and support become signals for the next version.
Work → evidence → story
The problem, build, failure and result become credible personal-brand content.
Distribution tools and current connections
The existing work includes a Reddit gallery renderer and one connected Instagram channel. No public post or schedule is claimed here. TikTok, Reddit and X hand-offs and automatic result ingestion remain planned.
Platform references: Instagram publishing, TikTok posting flows, Reddit API requirements, and X post creation. Connection and publishing rules differ by platform. The intended savings from reusing build material for distribution have not yet been measured.
Short notes on building AI agents in production.
One email when something worth sharing ships. No fluff, no daily cadence, no recycled growth-thread noise.
Primary use: site updates, governed AI workflow lessons, and major project writeups.